 Grace Priscilla Teo · · 6 min read
Feeding your AI less information might be the smarter move
This article summarizes an episode of AI Engineer’s video series featuring Nupur Sharma, solutions engineer at Qodo.
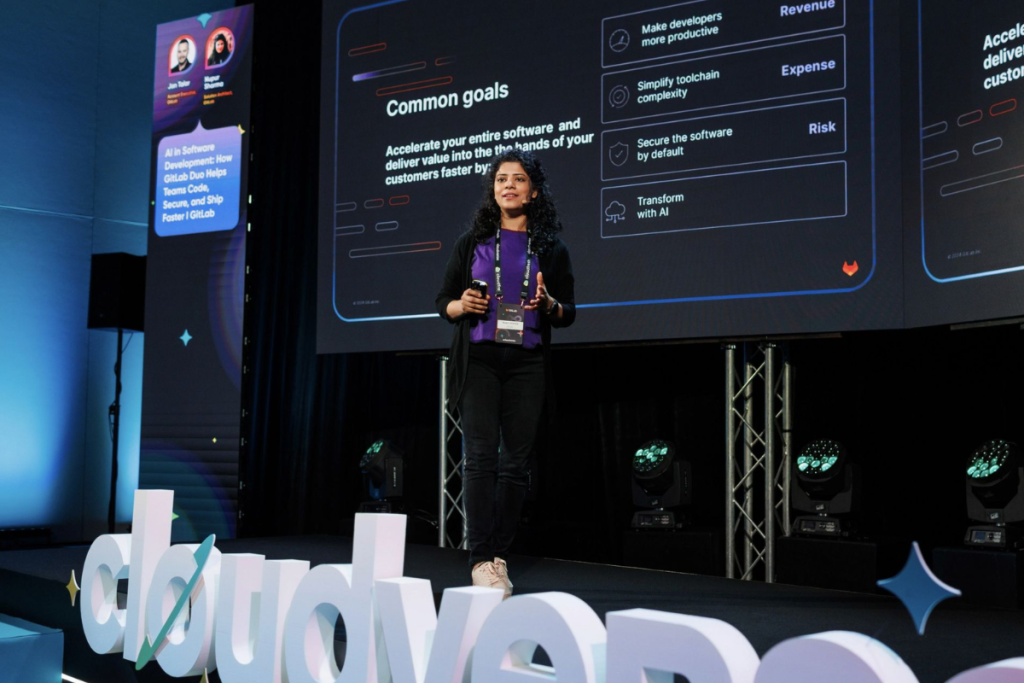
Nupur Sharma, Qodo solutions engineer/ Photo credit: Nupur Sharma
Tech companies often assume feeding an AI program more data ensures better results, and engineers expect providing a tool’s entire codebase history will produce perfect answers.
Qodo solutions engineer Nupur Sharma argues that supplying AI tools with too much information makes them less reliable.
Overwhelming a system with documents causes it to miss critical instructions, creating severe management hurdles for teams automating their workflows.
Large reading limits cause models to forget the middle
Expanding the text limit simply gives the software more room to skip crucial details, allowing that project notes and critical facts buried in the middle of files vanish from the final output.
Overcoming this structural blind spot requires teams to preprocess evidence before the model begins its analysis, organizing data through distinct methods that account for how AI actually reads:
- Prioritizing placement: Adding text helps only when evidence appears near the beginning or end of a prompt, as information stuck in the middle loses influence.
- Consolidating scattered facts: Code reviews highlight this failure because critical data sits scattered across history logs, linked work notes, connected files, and team habits.
- Sorting evidence upfront: Searching, scoring, summarizing, and testing must happen before the model starts processing rather than acting as afterthought additions.
Managing blind spots in reading comprehension
Engineers often blame poor results on a lack of memory, assuming the software simply needs more room to read the codebase.
Yet the failure originates in the program’s attention mechanism, which routinely abandons facts located in the center of a document.
“Context is not a problem,” Sharma points out, emphasizing that attention limits rather than storage capacity represent the true bottleneck.
Sorting information creates new expenses
Because models ignore the center of a document, upfront data sorting becomes mandatory. This shifts the primary expense from expanding memory limits to funding the computing power required for data organization.
Sorting strategies place workloads in different areas, requiring new servers, manual rule creation, or extra processing time on the final answer:
- Scaling search and scoring: These approaches work well in messy projects but slow down when scaling up to hundreds of folders.
- Layering summaries: Turning files into compact maps reduces the reading load but requires repeated processing whenever underlying files change.
- Building logic maps: Tracing how one file affects others demands intense initial effort and additional server capacity.
- Executing self-correction: Adding a testing step checks the result against the original goal, lowering the risk of the model wandering off topic.
The split model turns exploration into a restricted resource
Specialized models require a final judge





Stay updated on the go with our mobile app.
Get latest insights with smoother, more personalized experience through TIA mobile app.






📅 Upcoming Events
22 October 2026
Payoneer x CSPN Summit 2026