If data is the “new gold,” then the world is rich with it.
Currently growing at a rate of 2.5 quintillion bytes every day, global data lends accuracy and depth to the decisions made by companies of all sizes worldwide.
“The most interesting thing to come out of the pandemic was the realization of how hungry companies are for data,” said Sveta Friedman, global general manager of data analytics at accounting software provider Xero.
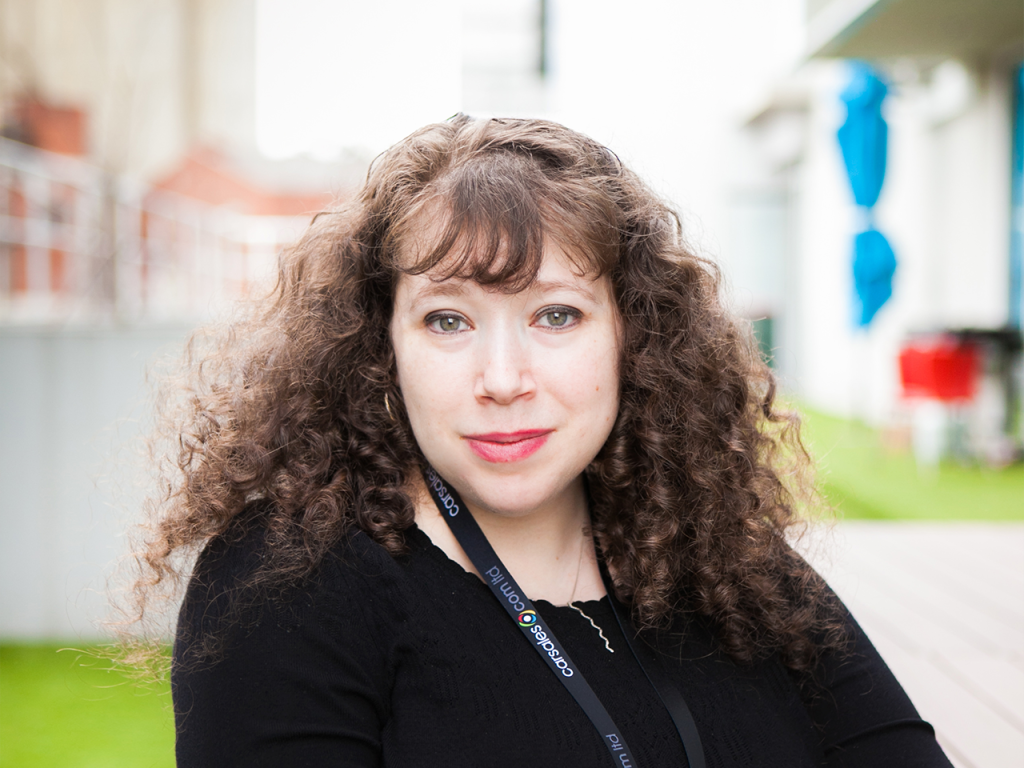
Sveta Friedman, global general manager of data analytics at Xero / Photo credit: Xero
Friedman was speaking at the Secure Hypergrowth Success through Data & AI Scalability event. Held on October 12, the virtual panel was organized by Tech in Asia in collaboration with Databricks, an AI-powered data analytics solutions provider.
The virtual panel discussion Friedman was participating in also featured data professionals from ecommerce rewards platform ShopBack and Databricks. The panelists explored how hypergrowth companies can accelerate their success by pairing data architecture with the right solutions and methodologies.
Deluge of data
The growing importance of leveraging information has led to an increasing need for data lakehouses, a solution that combines the structures used in data warehouses with the management features of data lakes.
Yet, the sheer volume of information being produced every day is also a double-edged sword for companies. Without the right processes or skills, a firm can be limited in how it uses data if there’s too much unstructured input.
Indeed, business intelligence firm Gartner warned that data lakes risked becoming “data swamps” if companies didn’t implement the necessary mechanisms to govern them, Kunal Taneja, senior director of field engineering at Databricks, said at the event.
This can lead to several major problems, which Taneja broadly places into two buckets: a lack of proper governance and misalignment with business values.
First, without highly skilled data professionals who can apply the right metadata, businesses will constantly have to start their data analysis from scratch, which makes capitalizing on it more trouble than it’s worth.
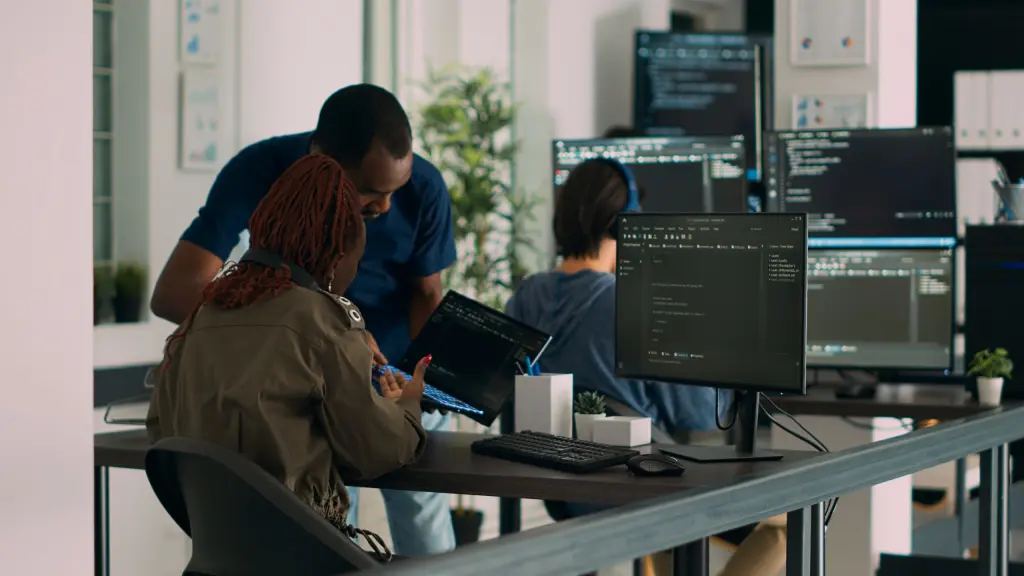
Photo credit: dragoscondrea / 123RF
“I’ve seen data products really fail because companies weren’t making sure the data they had was high-quality,” Taneja said, noting that this problem is especially common in banks. “After a while, the business side won’t trust their own data and end up looking for other sources of information.”
The second stumbling block is that data teams tend to hyperfocus on the technical aspects of a product at the cost of business realities.
“I’ve seen this happen where companies decide to build a deep learning model for every customer even though the economics of it just didn’t make any sense,” he said. “That’s a failure to stand up to what business value can be achieved, leading to a very good chance that a product will be a failure.”
Closing the data gap
The panelists at the Tech in Asia and Databricks event noted that there are ways around these common mistakes.
Xero’s Freidman advised companies to accept that failure is part of the process and to keep an eye out for existing solutions in the market that they can build on.
One such solution is AI, which introduces structure and automates many of the processes that help make sense of data.
To illustrate this relationship, Taneja offered a case study that Meesho, an Indian ecommerce platform, has shared at events before. More specifically, the case study showed how the firm successfully translated its customers’ transaction data into personalized recommendations. For instance, one customer’s browsing history for red shirts helped the company make accurate recommendations for other colors, leading to a 120x increase in query volumes within a year.
Additionally, Yann Aïtbachir, ShopBack’s head of data, suggested that companies need to improve their organization’s overall data approach by emphasizing four main pillars: data professionals, data-driven decision-making processes, data technologies, and the overall company culture.
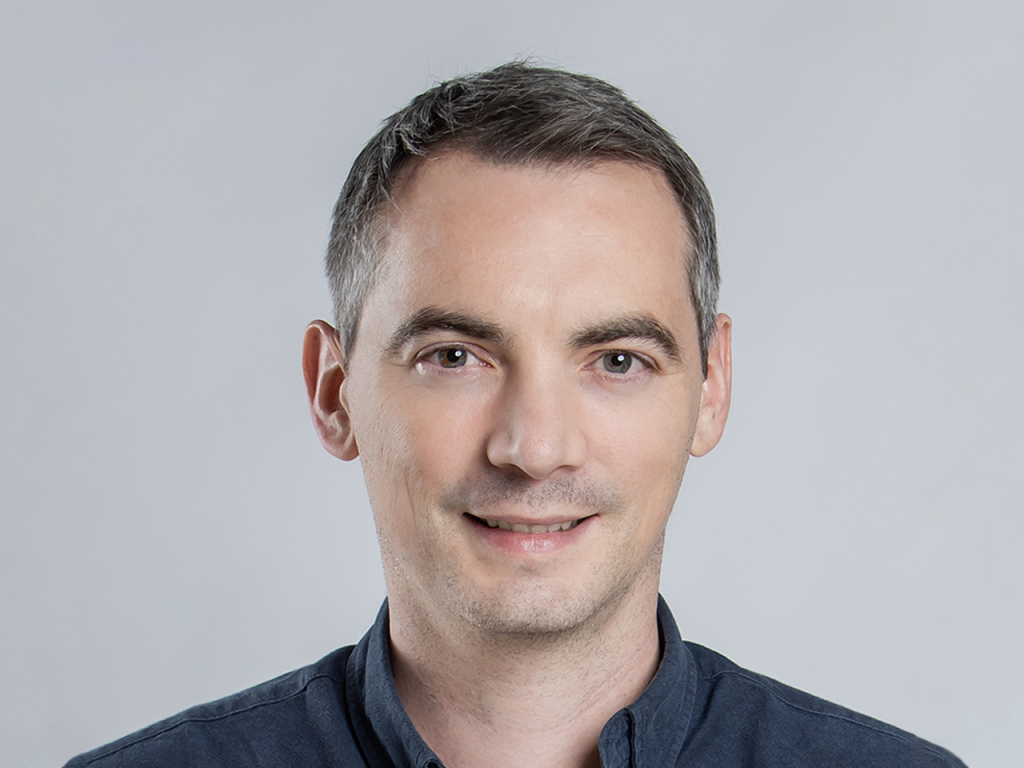
Yann Aïtbachir, ShopBack’s head of data / Photo credit: ShopBack
“At the hypergrowth stage, what really matters is how you empower everyone with autonomy, access, and support so they can use data to improve the decision-making process,” he said.
Freidman agreed and emphasized that democratizing data access must go hand-in-hand with a mature governance framework.
“Maturity is measured by how clean your data is, how much knowledge and capability the business has to utilize AI and machine learning,” she said. “It’s not just about technical skill but also responsibility and ethics.”
Even with the right tools and people, companies need to make sure they get the “foundations of their data lakes right” to ensure trustworthy data. Taneja emphasized.
Exciting developments on the horizon
Taneja predicted that the next several years of data innovations will be characterized by the rise of the “multicloud,” solutions that can work across different cloud computing service providers. This will be especially relevant in Southeast Asia, where providers are unevenly scattered.
“I also think there is too much of a blocker to get started with data-AI, so there is scope for a lot of self-service tooling for companies to pick it up,” he said. “I’m seeing innovation in enabling companies to start on this journey.”
Aïtbachir was excited at the possibilities enabled by the developments in AI to improve decision-making through simulations.
“Let’s say on ShopBack we want to decide whether to use a blue or red button – AI can help us generate synthetic data on both options without having to actually run the test on our product,” he shared. “That will have a dramatic change on how we approach data decisions in a hypergrowth-stage company.”
For Freidman, the engines of the industry’s development are the new data tools and platforms that are still in development – they’ll drive new efficiencies without requiring additional maintenance or engineering.
“We’ll continue to create more automation and features that will make it easier to deploy business solutions,” she concluded. “This space has been amazing in terms of how fast it’s matured over the last five to seven years.”
Databricks is a leading provider of data and AI knowledge. Its lakehouse architecture unifies the best of data warehouses and data lakes on a single platform that powers hypergrowth companies’ analytics, business intelligence, and AI needs. Its technology simplifies the modern data stack to eliminate silos, maximize flexibility, and ensure consistency across cloud providers.
Find out more about how Databricks can help you on your data journey on its website.
This content was produced by Tech in Asia Studios, which connects brands with Asia’s tech community. Learn more about partnering with Tech in Asia Studios.
Stay updated on the go with our mobile app.
Get latest insights with smoother, more personalized experience through TIA mobile app.
Recommended reads
 Alibaba’s capex isn’t the full story
 Forget startups. Buy the business running on Excel
 Life’s a game, and AI agents are Animoca’s new play
 Indonesian AI startup goes global
 Forrest Li on scaling Sea, building smarter bots, and founder grit
 An AI assistant that joins sales calls and scores team skills
 Beyond the check: Why VCs need more than capital
 SGX’s CEO says it doesn’t need a unicorn to win
 SMEs want AI too, but not the kind Big Tech is selling
 Oatside’s alt-milk rise hits a profitable gear
Editing by Jonathan Chew, Winston Zhang, and Jaclyn Tiu
(And yes, we’re serious about ethics and transparency. More information here.)