Pradeep Menon · · 6 min read
Data science simplified: Statistical learning you can understand
In the first article of this series, I touched on key concepts and processes of data science. In this article, I will dive a bit deeper. First, I will define statistical learning. Then, I will dive into its key concepts. Believe me, it’s simple.
What is statistical learning?
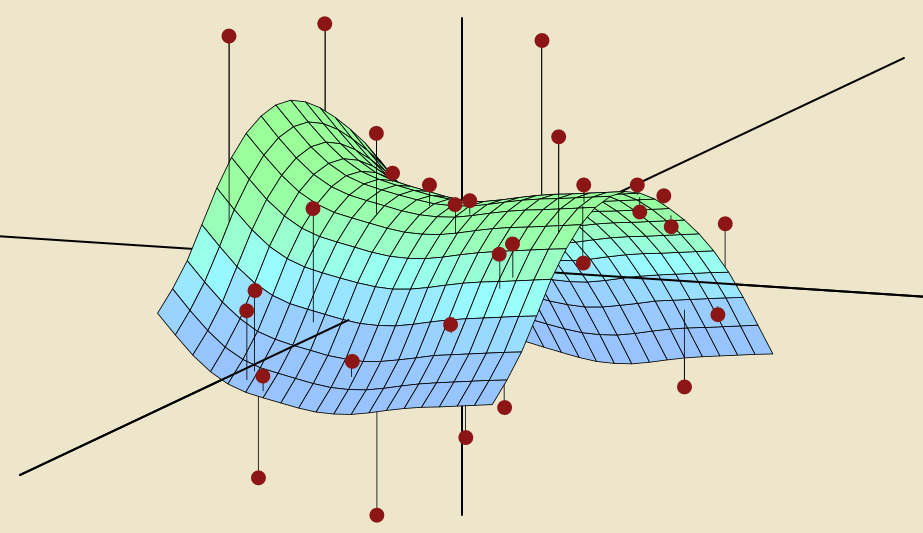
As per Wikipedia, the statistical learning theory is a “framework for machine learning, drawing from the fields of statistics and functional analysis.”
Machine learning is a manifestation of statistical learning techniques that are implemented through software applications.
What does this mean in practice? Statistical learning refers to tools and techniques that enable us to understand data better. Let’s take a step back here. What do we mean by understanding data?
In the context of statistical learning, there are two types of data:
- Data that can be controlled directly (aka independent variables)
- Data that cannot be controlled directly (aka dependent variables)
Dependent variables need to be predicted or estimated.
Understanding data better is to figure out more about the dependent variable in terms of independent variables. Let me illustrate it with an example:
Let’s say I want to measure sales based on the advertising budget I allocated for TV, radio, and print. I can control the budget that I assign to each medium. What I can’t control is how they will impact sales. I want to express data that I can’t control (sales) as a function of data that I can control (advertising budget). I want to uncover this hidden relationship.
Statistical learning reveals hidden data relationships—relationships between the dependent and the independent data.
Parameters and models
One of the famous business models in operations management is the Input-Transformation-Output (ITO) model. It is simple: there are inputs and they undergo some transformations then, an output is created
Training and testing
Variance and bias
Bias-variance trade-off
Conclusion





Stay updated on the go with our mobile app.
Get latest insights with smoother, more personalized experience through TIA mobile app.