- Premium Content It takes our newsroom weeks - if not months - to investigate and produce stories for our premium content. You can’t find them anywhere else.
 Scott Shuey · · 6 min read
Meta and X couldn’t stop Bright Data’s bots. Can Cloudflare do it?
After two years in courtrooms fighting Meta and X for the right to collect publicly available data on the internet, Bright Data thought it finally had the green light. Then Cloudflare installed a toll booth for AI bot crawlers.
Based in Israel, Bright Data has long drawn scrutiny from web platforms for scraping, which is the mass and automatic collection of data from websites.
Image credit: Timmy Loen
In 2023 and 2024, Meta and X – two of Bright Data’s former clients – filed lawsuits against the company, alleging that its tools violated terms of service and accessed user data without permission.
In both cases, California courts sided with Bright Data, ruling that scraping public data is legal under existing US law. The courts also found that it isn’t illegal to bypass anti-bot measures like CAPTCHA to access that data.
But starting in July, Cloudflare, a website and app infrastructure company, began blocking AI bots by default on client websites, unless site owners explicitly allow them.
The change introduced a new monetization option: a “pay-per-crawl” model that lets publishers charge AI firms for access to public web content. Cloudflare says the move is a response to increasing bot traffic.
While the company hasn’t linked its new policy to the recent lawsuits, Cloudflare maintains business ties with both Meta and X.
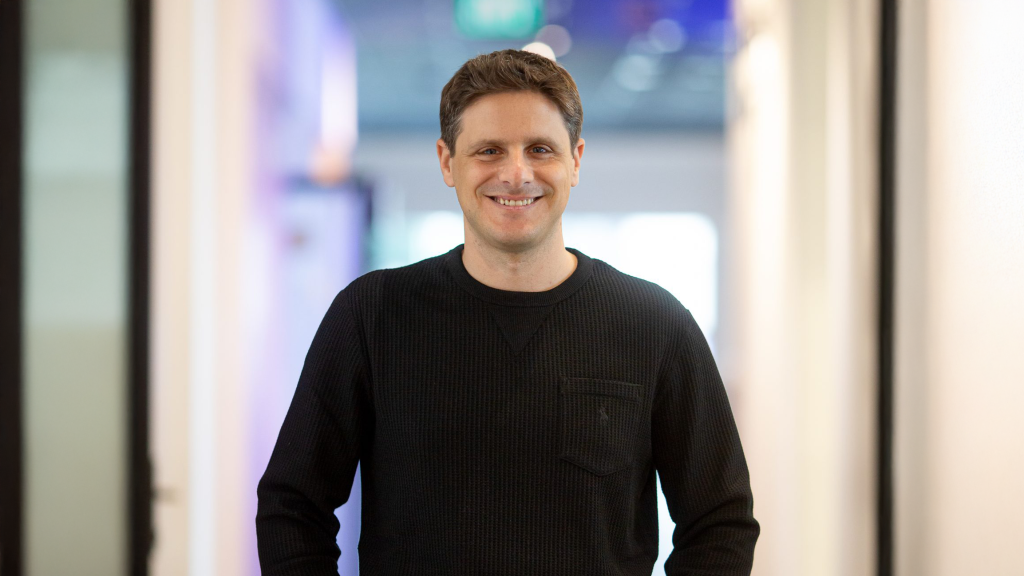
Or Lenchner, CEO of Bright Data. / Photo credit: Bright Data
In response, Bright Data published a blog post detailing how to bypass Cloudflare’s protections, underscoring the technical complexity and legal ambiguity at the heart of the debate over public web data access.
This fight isn’t just about data: it’s about control of the internet in the age of AI.
Clash for the data motherlode
Ecommerce platforms scrape public data to monitor competitor pricing. Financial institutions scrape forums and social platforms to learn consumer sentiment. And AI companies do it to train and fine-tune language models.
As a result, the business demand for publicly available web data has doubled from an estimated 320 terabytes in 2021 to over 800 terabytes in 2024, according to Common Crawl.
From VPN to data infrastructure
Who’s data is it anyway?
Why Cloudflare matters
Stay ahead in Asia’s tech landscape
This is premium content. Subscribe to read the full story.
Bright Data’s court wins have signaled that the web is open for scraping. Cloudflare’s new paywall asks: who really controls the data fueling the AI economy?
We know this is not ideal. ⌛ Sign up in 20 seconds. Cancel anytime.
Our subscriber community includes professionals from these companies:





Stay updated on the go with our mobile app.
Get latest insights with smoother, more personalized experience through TIA mobile app.