Embedded LLM hosts regional vLLM series to accelerate ASEAN AI infrastructure
ℹ️ News provided by: Embedded LLM
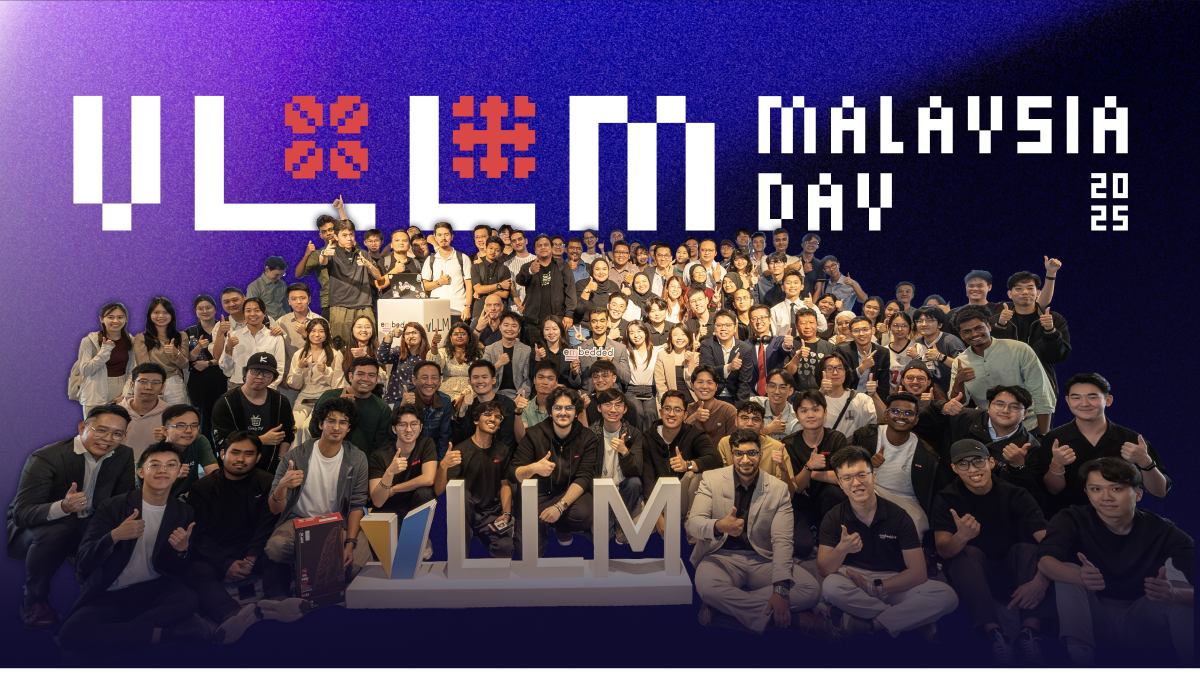 vLLM Malaysia 2025: Group Photos
MALAYSIA, 8 December 2025— With Southeast Asia seeing a rise in localized AI development, Embedded LLM, in collaboration with AMD, RedHat, WEKA, Tensormesh and national partners, successfully concluded a dual-city technical series in Kuala Lumpur and Bangkok aimed at strengthening open-source inference infrastructure.
The initiative, comprising “vLLM Malaysia Day” on December 2 and “vLLM Meetup Bangkok” on November 21, brought together over 500 enterprise architects, policymakers, and engineers. The sessions focused on the critical software layer required to run sovereign Large Language Models (LLMs), such as Malaysia’s MaLLaM and Thailand’s Typhoon and PathummaLLM, OpenThaiLLM, efficiently on local hardware.
From API Consumption to Infrastructure Optimization
As the region shifts from consuming external APIs to hosting sovereign models, the demand for high-performance serving engines has surged. Embedded LLM, serving as a contributor and maintainer of the vLLM project, utilized these sessions to transfer deep technical knowledge directly to the ASEAN developer community.
In Kuala Lumpur, supported by the Malaysia Digital Economy Corporation (MDEC), the discussions centered on “Data-First Deployment” for regulated industries. Ir. Wan Murdani Wan Mohamad, VP of Digital Adoption at MDEC, officiated the event, highlighting the necessity of robust digital infrastructure for the national roadmap.
Bridging the Hardware-Software Gap
The series addressed the specific engineering challenges of optimizing inference throughput. By bringing maintainers and LLM inference engineers directly to the region, the events bridged the gap between global open-source standards and local implementation.
Technical highlights included:
- Embedded LLM: Tun Jian Tan, vLLM Maintainer, presented “The State of vLLM,” outlining the future of high-performance inference, and led a deep dive on LMCache, demonstrating how optimizing KV cache sharing can drastically reduce latency and costs in production.
- AMD: Showcasing the integration of open software stacks with GPU and leading a hands-on workshop on building multi-agent systems.
- WEKA: Introduced distributed KVCache solutions to handle the massive context windows required by agentic AI.
- SCB 10X & NECTEC (Thailand): Presenting architectural strategies for training and serving Thai-language models.
- Mesolitica (Malaysia): Discussing the deployment of MaLLaM for enterprise-grade workloads.
“Connecting global standards with local builders is essential for the region’s growth,” said Muhammad Usman, Head of Ecosystem and Partnership at Embedded LLM. “These events provided the technical blueprint for organizations looking to optimize their own AI infrastructure using open-source tools.”
About Embedded LLM:
Embedded LLM is a deep-tech company building the software for the global AI ecosystem. As a core contributor and maintainer of the vLLM project, it collaborates with the community to drive critical infrastructure development, from kernel optimization to upstream model support, enabling enterprises to run models faster and cheaper. Specializing in high-performance infrastructure software, the company offers TokenVisor for GPU monetization and JamAI Base for agent orchestration. Headquartered in Singapore, it operates globally across Malaysia, Taiwan, and EU.
For more information, please contact: